Anticipate information needs
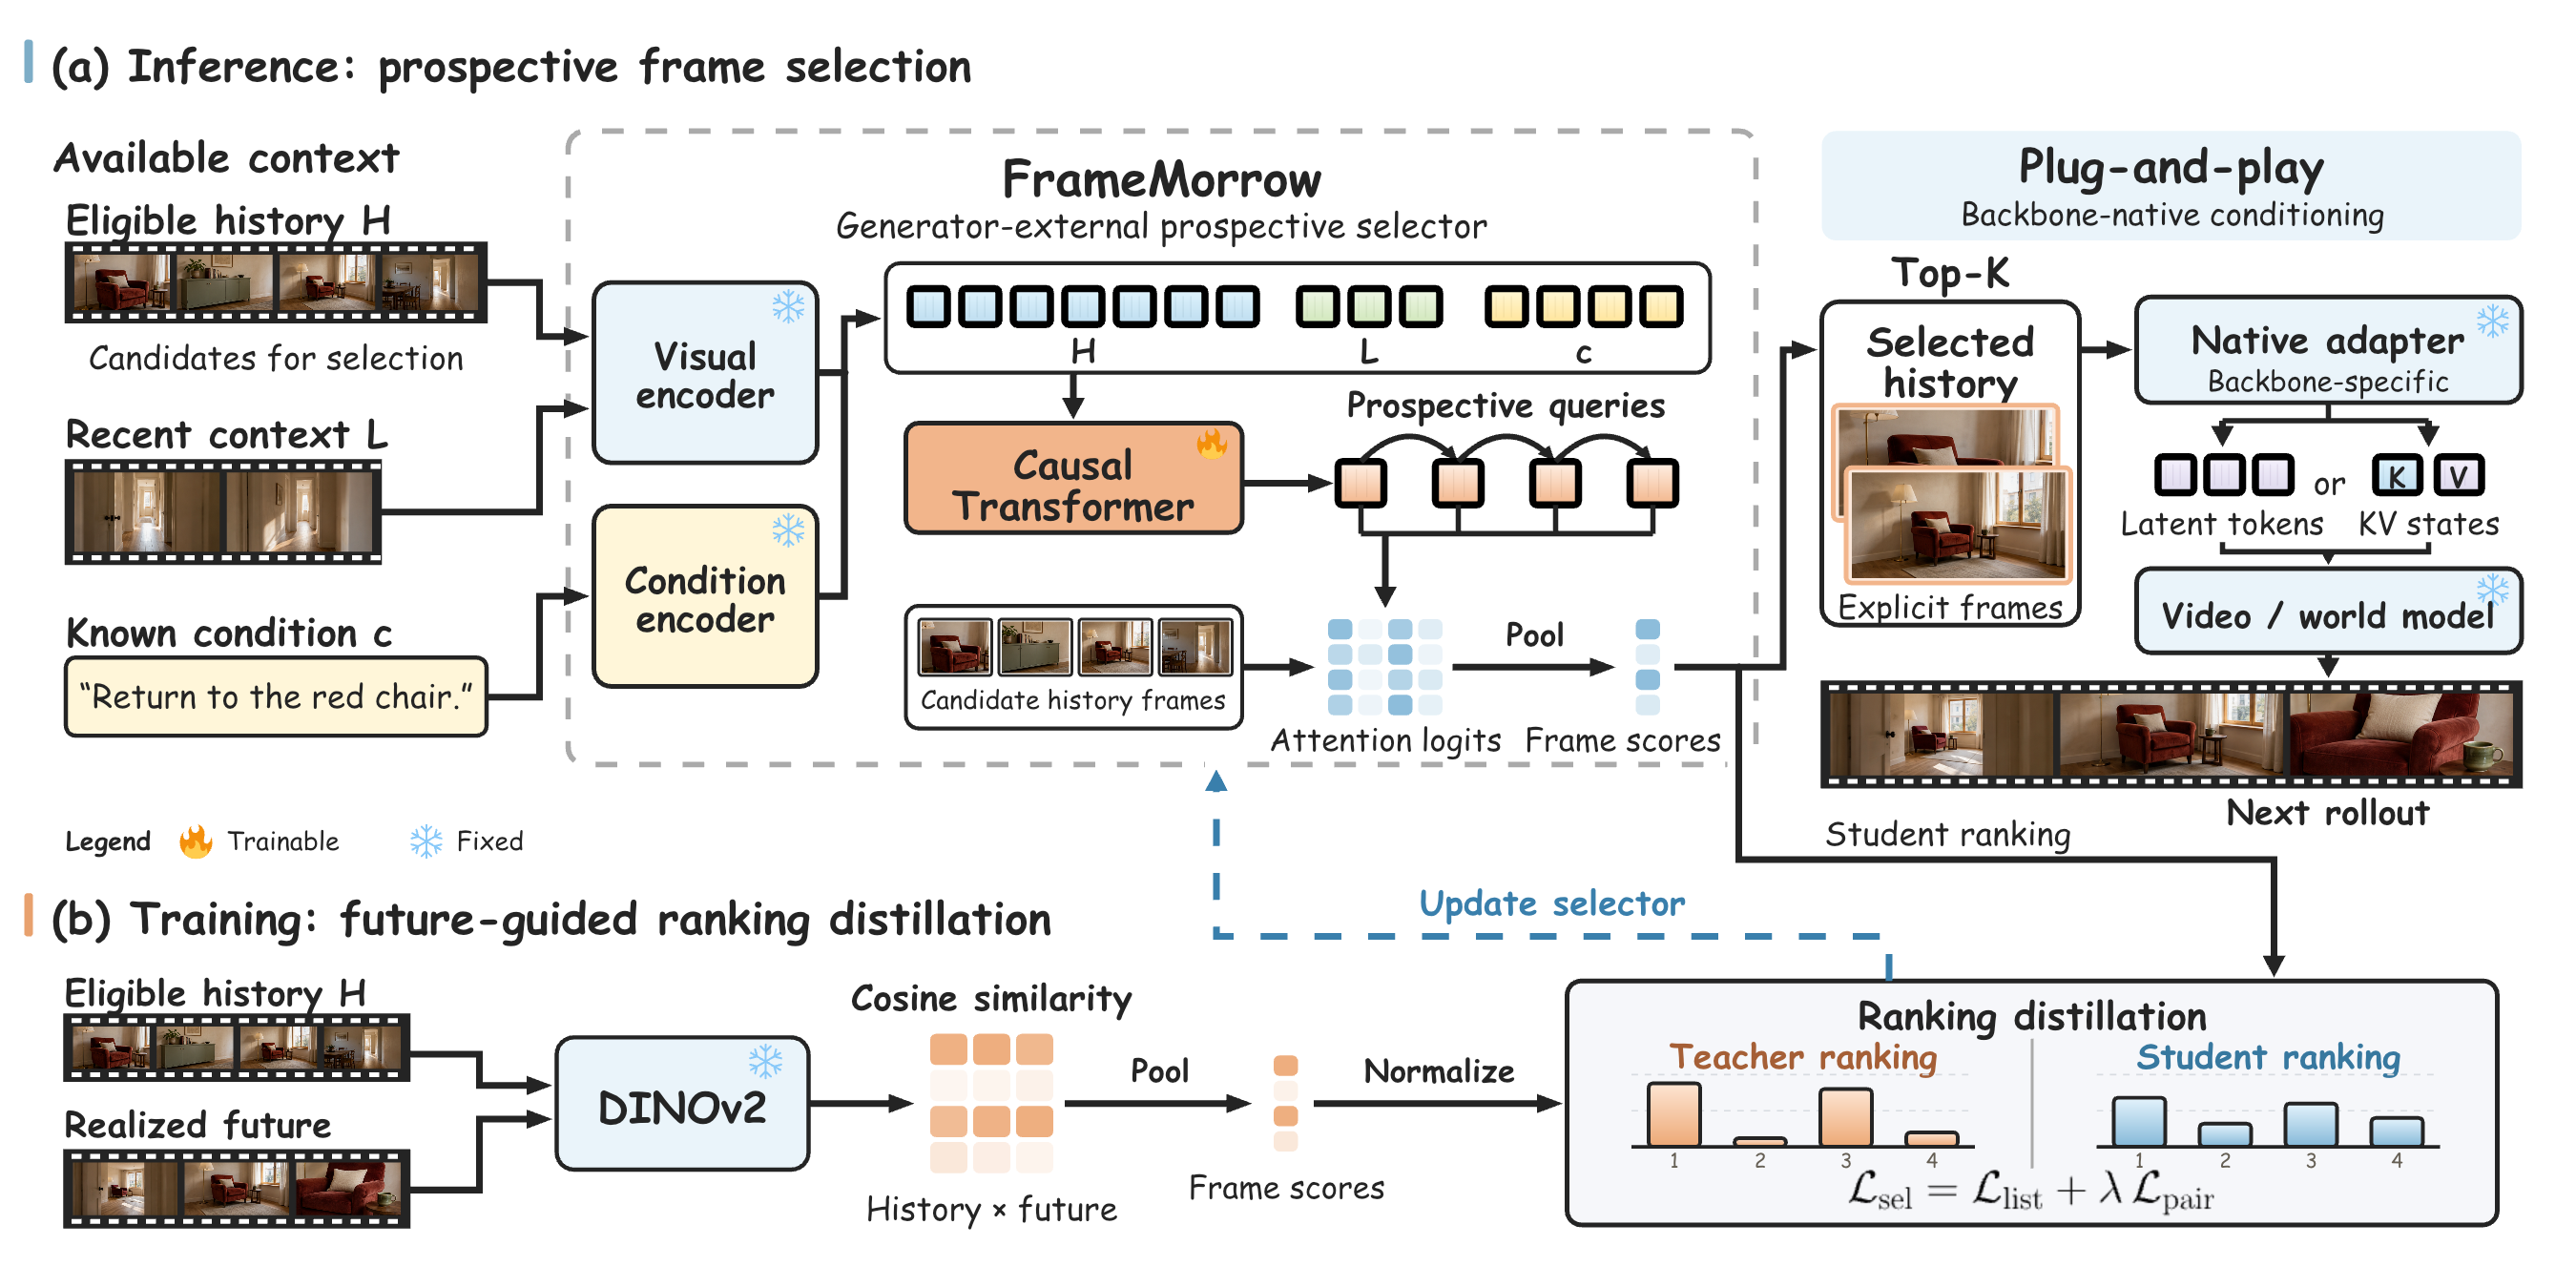
Prospective tokens summarize what may matter next, using available history, recent context, and the generation condition.
A memory for what comes next
Future-Guided Frame Selection with Prospective Tokens
for Long-Horizon Video Generation
See the difference
Native generation alongside
generation with FrameMorrow.
Follow the subject and scene as the video progresses. Both videos use Causal Forcing, with historical frame selection added on the right.
Synchronized playbackThe intuition
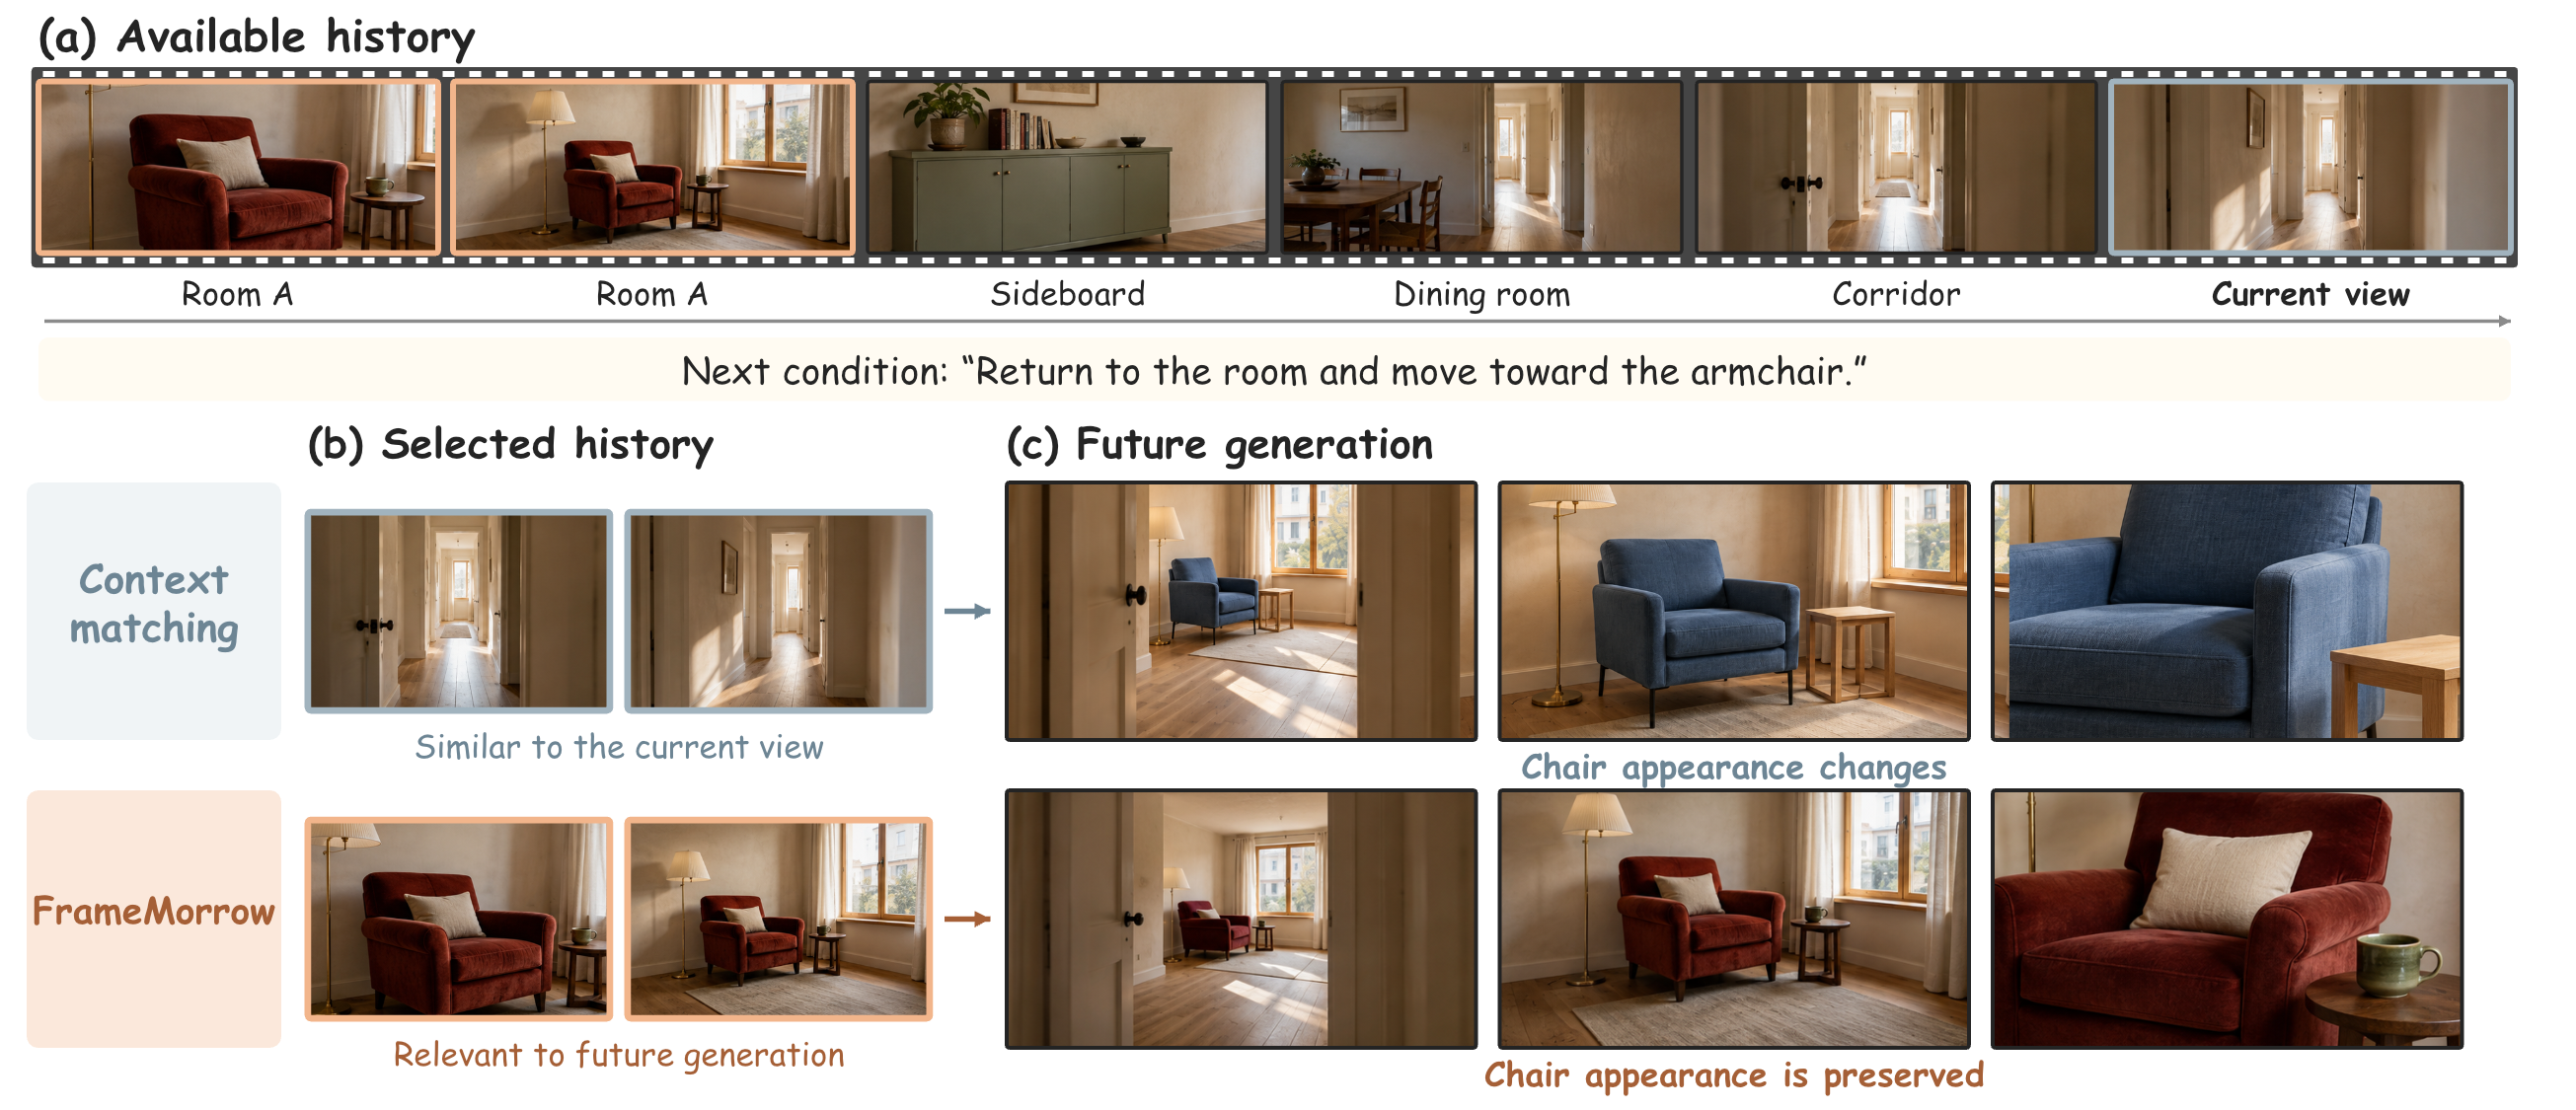
Select history for future needs.
A corridor may match the current view. But returning to a room requires remembering its earlier appearance. FrameMorrow learns to retrieve historical evidence for the upcoming generation.
A compact future proxy
No full future rollout required.
Prospective tokens summarize what may matter next, using available history, recent context, and the generation condition.
The tokens score historical candidates. A small set of selected frames carries relevant visual evidence forward.
Selected frames enter each backbone through its own conditioning interface. The selector stays outside the generator.
Quantitative results
Orange rows: + FrameMorrow
↑ Higher is better · ↓ Lower is better
| Model / method | Subject ↑ | Background ↑ | Motion ↑ | Dynamic ↑ | Aesthetic ↑ | Imaging ↑ | Avg. rank ↓ |
|---|---|---|---|---|---|---|---|
| Self-Forcing | |||||||
| Native | 95.84 | 95.27 | 98.20 | 51.72 | 56.05 | 62.22 | 4.33 |
| +∞-RoPE | 97.24 | 96.24 | 98.58 | 46.64 | 56.09 | 63.28 | 3.17 |
| +Deep Forcing | 96.08 | 95.38 | 98.24 | 41.44 | 56.68 | 60.81 | 4.17 |
| +LongLive-RAG | 97.60 | 96.51 | 98.70 | 44.69 | 57.19 | 64.97 | 2.00 |
| +FrameMorrow | 97.71 | 96.45 | 98.60 | 64.56 | 57.27 | 68.47 | 1.33 |
| LongLive 1.0 | |||||||
| Native | 97.13 | 95.89 | 98.61 | 44.56 | 58.17 | 67.56 | 3.83 |
| +∞-RoPE | 97.00 | 95.85 | 98.53 | 53.36 | 57.48 | 66.94 | 4.25 |
| +Deep Forcing | 97.17 | 96.04 | 98.73 | 45.13 | 57.48 | 67.27 | 3.42 |
| +LongLive-RAG | 97.32 | 96.08 | 98.62 | 49.90 | 58.30 | 67.79 | 2.25 |
| +FrameMorrow | 97.32 | 96.17 | 98.75 | 50.42 | 58.75 | 67.82 | 1.25 |
| Causal Forcing | |||||||
| Native | 93.52 | 94.12 | 95.74 | 72.32 | 51.24 | 62.30 | 4.83 |
| +∞-RoPE | 93.81 | 93.78 | 96.09 | 92.47 | 54.42 | 67.50 | 3.33 |
| +Deep Forcing | 94.27 | 94.18 | 96.62 | 78.59 | 52.12 | 64.25 | 3.17 |
| +LongLive-RAG | 94.29 | 94.24 | 96.48 | 88.20 | 54.95 | 68.16 | 2.33 |
| +FrameMorrow | 94.54 | 94.28 | 96.59 | 89.74 | 56.27 | 68.76 | 1.33 |
Bold marks the best score within each backbone. Average rank is computed across the six metrics; lower is better.
| Model / method | Quality ↑ | Consistency ↑ | Aesthetic ↑ | Avg. CLIP ↑ |
|---|---|---|---|---|
| Single-shot | ||||
| LongLive 1.0 | 83.49 | 92.62 | 64.21 | 28.75 |
| +FrameMorrow | 84.06 | 93.21 | 64.56 | 29.08 |
| Self-Forcing | 78.71 | 84.95 | 58.16 | 26.39 |
| +FrameMorrow | 81.74 | 89.30 | 60.62 | 28.05 |
| Causal Forcing | 76.00 | 80.46 | 55.45 | 24.53 |
| +FrameMorrow | 78.66 | 83.48 | 58.75 | 25.24 |
| CausVid | 81.94 | 89.77 | 63.53 | 28.63 |
| +FrameMorrow | 82.26 | 90.52 | 63.64 | 29.03 |
| Multi-shot | ||||
| LongLive 2.0 | 82.77 | 93.14 | 61.32 | 28.35 |
| +FrameMorrow | 83.18 | 93.49 | 61.68 | 28.44 |
| ShotStream | 83.12 | 92.75 | 62.30 | 29.09 |
| +FrameMorrow | 84.85 | 96.76 | 61.74 | 29.16 |
Bold marks the better score within each backbone pair. Average CLIP score summarizes six consecutive 10-second segments.
| Model / method | Subject ↑ | Background ↑ | Imaging ↑ | Anti-flicker ↑ | Motion ↑ | Action alignment ↑ |
|---|---|---|---|---|---|---|
| Matrix-Game 3.0 | 0.801 | 0.894 | 68.20 | 0.936 | 0.950 | 0.842 |
| +FrameMorrow | 0.816 | 0.910 | 68.35 | 0.939 | 0.949 | 0.861 |
| WorldMem | 0.782 | 0.924 | 70.23 | 0.910 | 0.916 | 0.866 |
| +FrameMorrow | 0.793 | 0.932 | 70.47 | 0.913 | 0.918 | 0.889 |
| YuMe 1.5 | 0.765 | 0.872 | 50.98 | 0.944 | 0.965 | 0.883 |
| +FrameMorrow | 0.798 | 0.886 | 51.80 | 0.947 | 0.967 | 0.912 |
Bold marks the better score within each backbone pair. Imaging uses a 0–100 scale; the other metrics lie in [0, 1].
One idea, multiple settings
Evaluated across long-video generation, interactive generation, and action-conditioned world models.